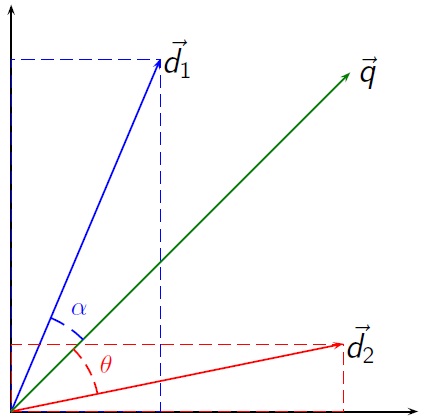
Cohere says its new Embed 5 models let a search system build a document index with Embed 5 Pro, then encode live queries with the lower-latency Embed 5 Fast without rebuilding that index. The two models share an embedding space, so their numeric representations can be compared.
An embedding model turns a document or query into a vector: a list of numbers that represents its content. A retrieval system compares the query vector with stored document vectors to find likely matches. When the two model versions share a space, the indexing and query workloads can use different tiers while keeping those representations compatible.
In Cohere’s cross-model evaluation across 40 development datasets, a corpus indexed with Pro and queried with Fast scored 98.4 when Pro-to-Pro was normalized to 100. The company says the tests covered text, image, mixed text-and-image, and parsed-document retrieval. This is a vendor-reported result; the article cites no independent reproduction.
The score has a narrower meaning than full search quality. Cohere’s RCP-nDCG@10 metric reranks a fixed set of candidate results, so it measures how well the models order retrieved candidates, not whether the first retrieval step found every relevant document. The comparison supports cross-model compatibility in that test, while teams still need to evaluate their complete pipeline on their own data.
Announced on September 30, Embed 5 is available through Cohere’s API, Microsoft Foundry, Amazon SageMaker, and Model Vault.
Image credit: Vector space model by Riclas, licensed under CC BY 3.0.

Sources